
Vision-Language Action (VLA) Models: The Brains Inside Humanoid Robots
A mechatronics engineer breakdown of Vision-Language-Action (VLA) models: Figure robot AI brain, Physical Intelligence Pi0, joint torque trajectories, and industrial dexterity.
- ✓Vision-Language-Action (VLA) models output motor control joint torques directly from visual camera feeds and natural language instructions.
- ✓Physical Intelligence Pi0 and Google RT-2 have bridged high-level reasoning with low-level robotic dexterity.
- ✓Embodied AI models generalize manipulation skills across novel objects without requiring custom kinematic reprogramming.
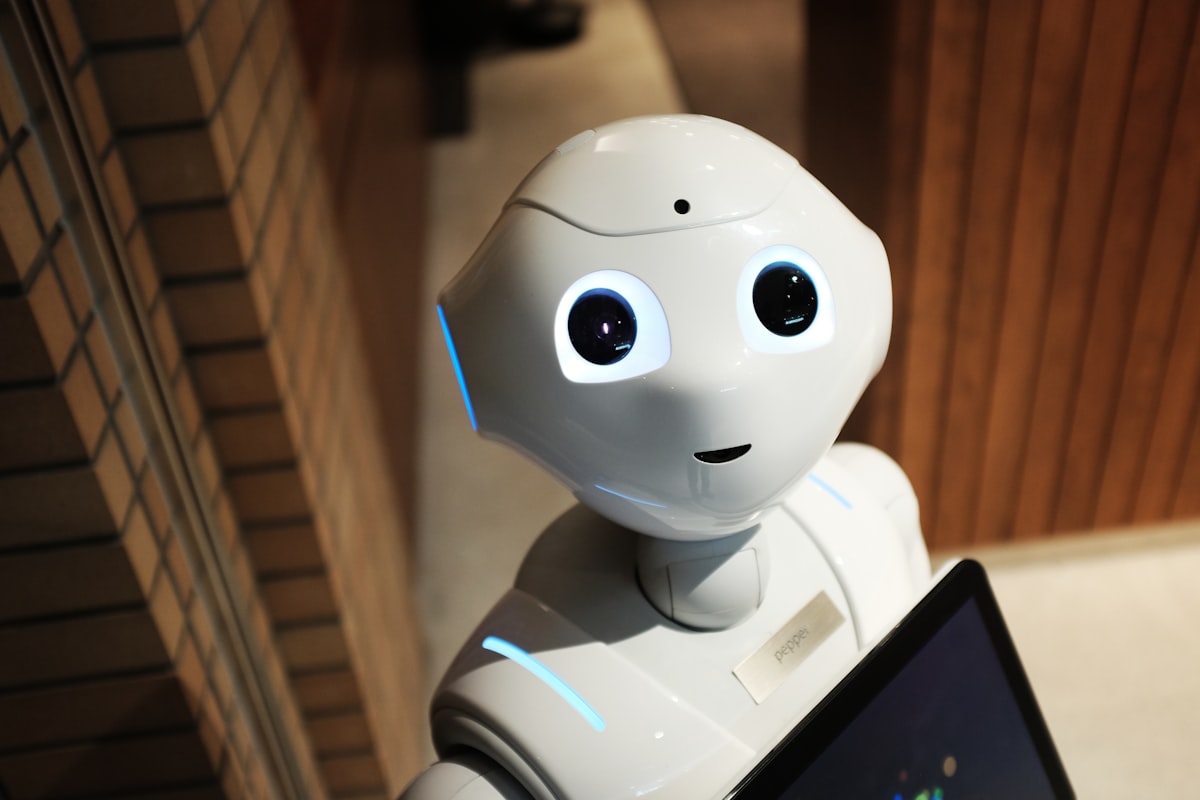
Vision-Language Action (VLA) Models: The Brains Inside Humanoid Robots
Industry Benchmarks • Architecture Review • FilxTech - AI & Enterprise Web Engineering Labs
1. The Mechanical Reality: Beyond Chatbots to Motor Torques
If you work in mechatronics and industrial automation, you know that physical reality has zero tolerance for hallucinations. In software, if an LLM generates a syntax error, your compiler throws an exception. In robotics, if your neural network miscalculates actuator torque on a six-axis robotic arm, you break a $15,000 harmonic drive gearbox or crush a fragile human hand on the assembly line.
For decades, robotics was crippled by rigid hard-coding: every angle, inverse kinematic equation, and gripper velocity had to be programmed by hand. If a cardboard box was tilted five degrees to the left, the robot failed. The emergence of Vision-Language Action (VLA) models—spearheaded by Physical Intelligence (Pi0), Google DeepMind (RT-2), and Figure AI—represents the monumental leap from language generation to physical embodiment.
2. The Execution Architecture: Pixels to 50Hz Actuator Control
How does a neural network convert English speech and camera pixels into robotic movement?
Visual Perception & Goal Understanding
Stereo RGB cameras capture the scene at 60fps while a natural language command arrives: "Fold the blue cotton shirt and place it in the wicker basket."
High-Level Spatial Reasoning
The transformer’s vision-language layers identify the shirt’s fabric wrinkles, the basket’s boundaries, and plans a multi-stage physical strategy.
Action Token Emission (Motor Trajectories)
Instead of generating text characters, the output layer emits continuous action chunks: 7-dimensional vectors specifying end-effector XYZ coordinates, pitch/yaw/roll rotations, and tactile grip pressure streamed to motor controllers at 50Hz.
3. The General-Purpose Robotics Era
The breakthrough demonstrated by Physical Intelligence Pi0 is cross-embodiment generalization: the exact same neural weights can control a bipedal humanoid walking across a warehouse, a tabletop robotic arm sorting silverware, or a dual-arm robot assembling automotive wire harnesses. We are witnessing the birth of general physical intelligence.
Frequently Asked Technical Questions
How does a Vision-Language-Action (VLA) model differ from a standard multimodal LLM?
While a standard multimodal model outputs text or code tokens, a VLA model outputs low-level actuator control tokens: 6-DoF end-effector positions, gripper open/close values, and continuous motor joint torques operating at 50Hz.
What is Physical Intelligence Pi0?
Pi0 is a general-purpose robotic foundation model developed by Physical Intelligence that can perform diverse dexterous physical tasks—folding laundry, clearing dishes, boxing items—across completely different robot hardware bodies.
What is the biggest challenge in scaling robotics foundation models?
The data bottleneck. Unlike text and images which are plentiful on the internet, physical robotic action data requires teleoperation demonstrations, hardware sensors, and complex real-world edge cases.

Authored by Israfil Hossain & FilxTech - AI & Enterprise Web Engineering Architects
Chief Executive Officer & Principal Architect
Technology visionary and lead software architect specializing in distributed cloud systems, high-concurrency web architectures, and mission-critical enterprise engineering. Need strategic review on your application roadmap?
Direct inquiry: filxtech.ceo@gmail.com
Execute This Architectural Blueprint
Whether deploying frontier LLM pipelines, autonomous coding agents, or scaling enterprise AI infrastructure, FilxTech - AI & Enterprise Web Engineering delivers battle-tested production software.